In August 1949 Norbert Wiener, the MIT mathematician who had just given cybernetics its name, wrote to Walter Reuther, president of the United Auto Workers. A large corporation had asked for his help with “servo-mechanisms”, machines that check what they are doing and correct themselves, and Wiener had turned it down. He could see that such machines would “lead to the factory without employees”, and he thought that “in the hands of the present industrial set-up” the unemployment they caused “can only be disastrous”. So he offered the union another route: it could “steal a march upon the existing industrial corporations” by taking part in making the machines, so that the profits went “to an organization dedicated to the benefit of labor”. He offered to help “without any demand or request for personal returns”.
I wrote about that letter recently, and what stays with me is the question underneath it: who should decide what a powerful new technology is used for? Seventy-seven years later the machines write and code, and the question has become sharper, because this time the machines were built out of us.
A technology people can learn
AI can look like it arrived out of nowhere with ChatGPT in 2022, but it has a long history. The field was named at a workshop at Dartmouth in 1956, and it grew up alongside cybernetics. However, the field went through long cold spells: in the US, the Mansfield Amendment of 1969 pushed military research money towards projects with direct defence uses, and in Britain the Lighthill report of 1973 led to deep cuts. For decades the ideas outran the hardware, until computing power and data finally caught up.
Graphics chips, designed for video games, turned out to be very good at the parallel arithmetic that neural networks need, and in 2012 a network trained on two of them won a major image recognition contest by a wide margin. In 2017 a paper called “Attention Is All You Need” introduced the transformer, the design behind almost every large language model today.
Seen this way, AI is the next step in a long story of machines that help us think, much as early computers changed how we work with numbers and, through them, how we do science. It carries real risks, and like electricity before it, it is a technology ordinary people can learn about, organise around and help to own.
We have seen this pattern before
We have already lived through one technology built out of what ordinary people put into it. Social media platforms were free to use, and in return we gave them our posts, photos, videos and conversations, along with a detailed record of how we behave online. That content is what made the platforms worth visiting, and some creators built real careers on it, but the platforms owned the data, set the rules and kept most of the earnings.
Social media helped people connect, publish and reach a global audience, and it also brought a great deal of psychological harm and manipulation. Part of the reason was that most of us accepted it on the terms we were given; another part was that the platforms were tuned to maximise engagement and advertising, and those goals steered everything else. In cybernetic terms, whoever sets what a system measures decides where it goes.
AI could follow a similar path, only faster. It can improve quickly through feedback loops fed by data and by our own use of it, so if we wait once again, any damage could come much sooner than it did with social media, and arguably go even deeper, into our work, our knowledge and our creative output.
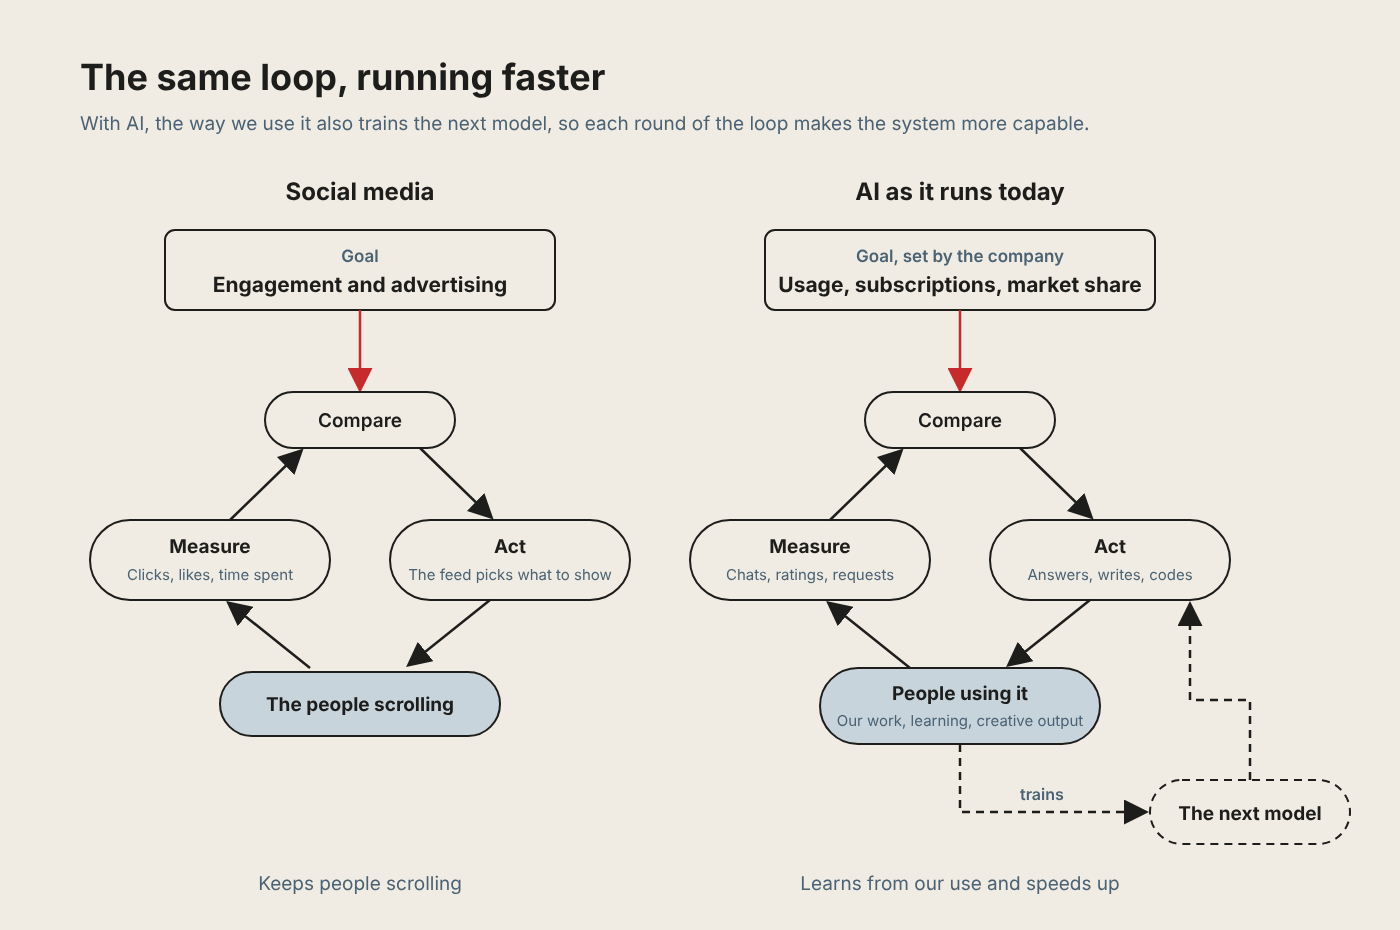
Rejecting AI outright has much the same effect as waiting. Decisions about it are left to the people building it, who are highly motivated to keep going and have their own agendas, which may not align with the interests of the people who will end up using it. It is worth remembering that when a founder or chief executive tells us what AI is, what it will do, or how frightened we should be. Some of the most serious warnings come from independent researchers, but some of the loudest hype and doom come from people with something at stake.
Regulation will help in places, though it moves far more slowly than the technology: the EU’s AI Act came into force in 2024 and is still being phased in. It is also written mostly by officials, technical experts and industry representatives, with ordinary people largely absent from the room, so it can end up protecting people in ways that do not match what they actually need. The cookie banner is a familiar example. EU privacy rules, tightened in 2009 and again by the GDPR in 2018, require websites to ask before tracking their visitors. The result is a pop-up on almost every site that most people click away without reading. For a large company this is a routine cost, but for an independent publisher who simply wants to know how many people read their work, it is one more technical and legal hurdle.
That leaves the steering to the rest of us, and we have a stronger claim than it might seem, because AI was built from what we wrote, posted and said.
Built from all of us
Large language models learn from enormous amounts of text: web pages, forums, encyclopaedias, news, code and books. Many of them draw heavily on Common Crawl, a public archive of billions of web pages written by people who never imagined their posts would train a machine. Books matter too. In the US case Bartz v. Anthropic, the judge accepted that buying print books and scanning them for training was lawful, but the company had also downloaded millions of pirated copies, and in July 2026 a $1.5 billion settlement with authors was approved, roughly $3,000 per book.
People also shape these models directly. After the first round of training, models are refined by human annotators and raters, who write example answers, rank responses and flag harmful content. Much of this work is contracted out around the world, often for little money: in 2023 TIME reported that Kenyan workers labelling disturbing content for OpenAI earned less than $2 an hour. In a way they resemble creators on social media: they are paid for what they contribute, but the company sets the rate and keeps the product.
The source that is easiest to overlook is the conversations we have with AI every day. Popular chat services such as ChatGPT and Claude can use those conversations to train future models unless users switch this off; Anthropic, for example, made it the default in 2025. Our chats show the companies what people actually ask for, where the models get things wrong and where users get frustrated, which is exactly the feedback needed to improve them. Every time we use these tools, we are helping to build the next version.
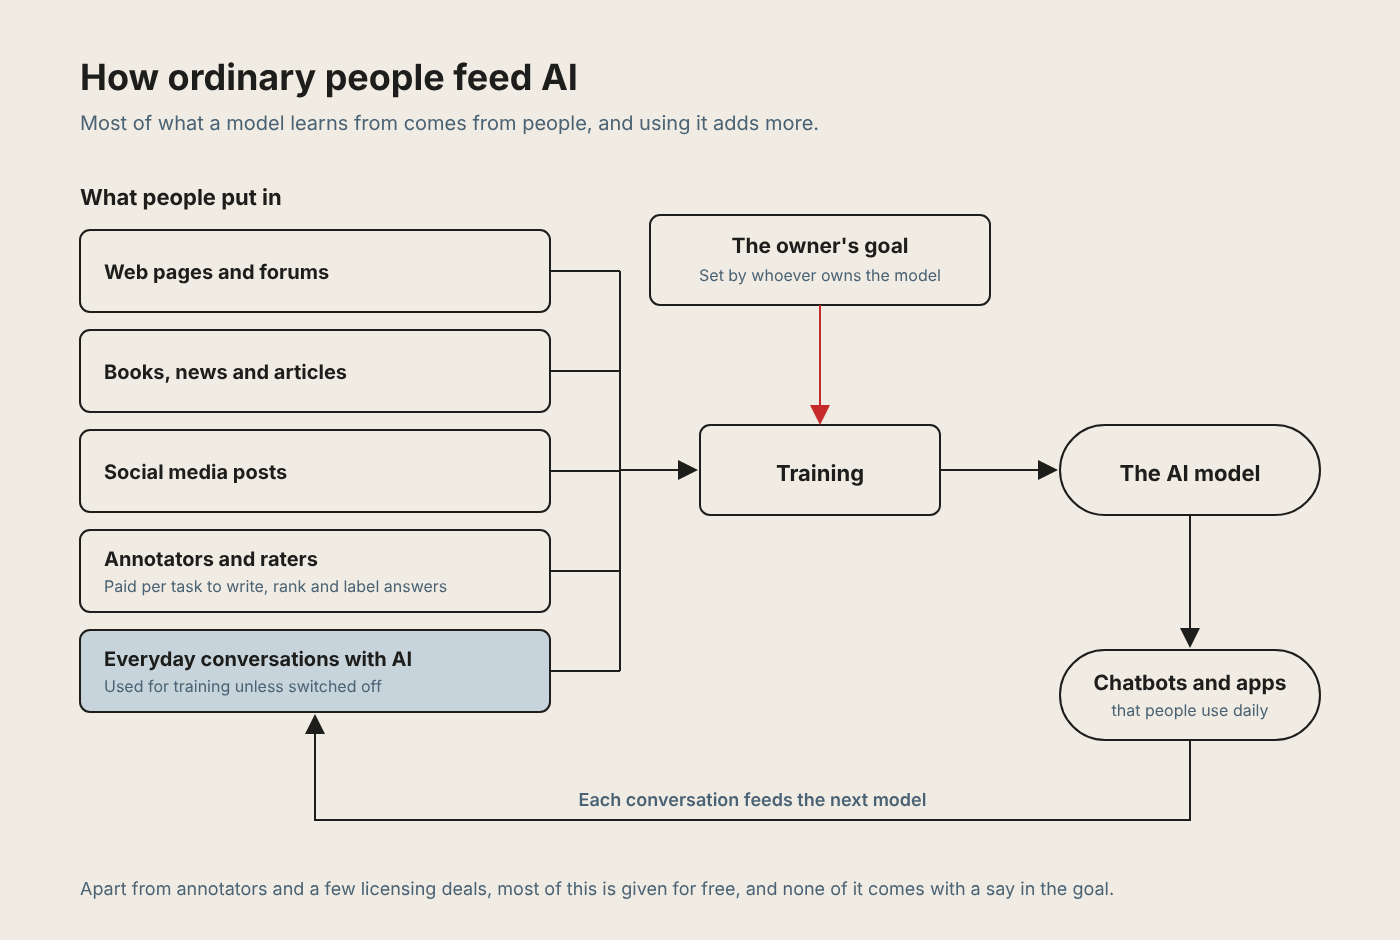
So, going back to the question from the title: if AI was trained on humanity’s knowledge, shouldn’t humanity own it? The moral case is strong, and it is easy to see why so many people feel that something has been taken from them. A lot of the anger around AI comes from here: work used without permission, memory and graphics card prices rising sharply as chip makers serve data centres first, rather than consumer markets, and a flood of cheap, low-effort content. Many of those objections are fair, and most of them come back to the same complaint: people helped build AI without being asked, and they have no say in what it becomes. The companies themselves talk the same language: OpenAI’s stated mission is to ensure that artificial general intelligence “benefits all of humanity”, and promises of shared benefit run through the industry’s marketing. The question is what a promise like that is actually worth.
Ownership, layer by layer
The promise to benefit humanity is made by the people who own the technology, and, as owners, they remain free to redefine it, delay it or drop it quietly. At its simplest, ownership is a bundle of rights: to use something, to decide what happens to it, to keep others out, and to take what it earns. Holding those rights is what turns a promise into a claim. So the real question is how humanity could hold that kind of claim on AI. Being “owned by humanity” could mean several different things, so it helps to take the idea of ownership apart. AI has layers: the energy that powers it, the computing power it runs on, the data it learns from, the trained models, and the services people actually use. Ownership cuts across all of them and can sit with different people at each one, so “who owns AI?” breaks down into five smaller questions: who supplies the energy, who owns the computing power, who controls the data, who holds the models, and who runs the services?
Who owns it today
At the moment the answer to most of these questions is much the same: a small number of companies. Underneath everything is energy. The International Energy Agency expects data centres’ electricity use to roughly double by 2030, to around 945 terawatt-hours, and the largest tech companies are now securing their own supply, as Microsoft did when it agreed to restart a reactor at Three Mile Island. A few chip makers and cloud providers supply most of the computing power. The data was largely taken from the public web, from books and from people’s posts, mostly without asking. The leading models belong to a handful of labs, and the services people use are mostly run by those same firms.
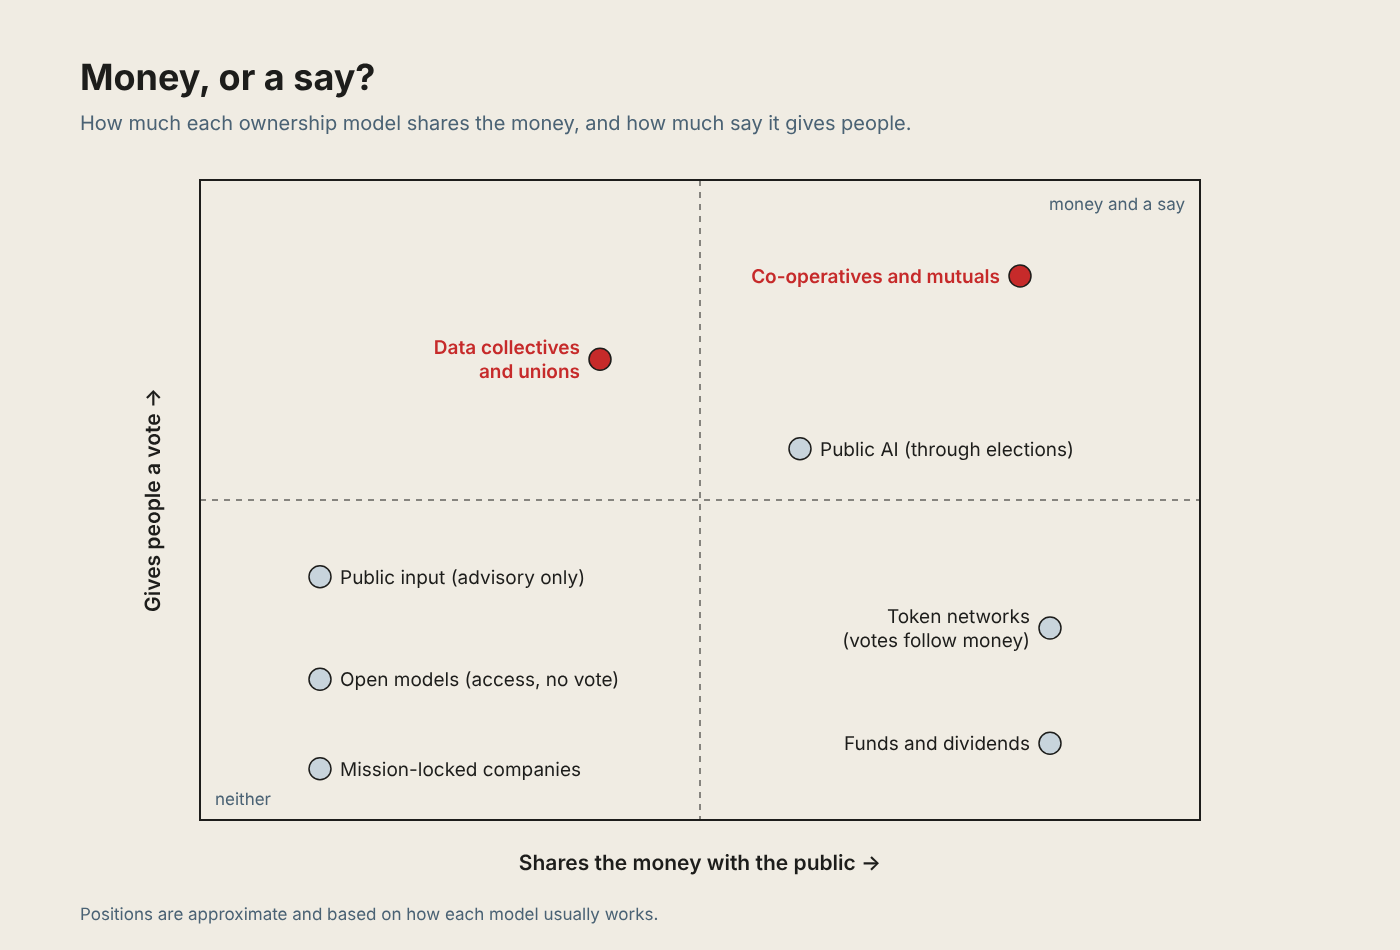
Some of these companies have tried to answer the ownership question themselves with a mission lock. OpenAI’s nonprofit foundation controls the board of its for-profit company and holds about a quarter of its shares, and Anthropic has a trust that elects a majority of its board. These arrangements are meant to protect a public purpose, but the public has no vote in them, and they can be renegotiated when enough money is at stake.
The alternatives on the table
Each of those questions has its own stakeholders, and several alternatives are already being tried or proposed. Let’s take a quick look at them.
Governments can build public AI. Switzerland’s universities released Apertus in 2025, a model whose code, training data and weights are all published, and the UK has committed £500 million to public supercomputers for researchers. Public AI is only as accountable as the government behind it, though, and it has to be good enough that people choose to use it.
Funds and dividends would share the wealth AI creates, much as Alaska has paid its residents a yearly dividend from oil since 1982. Researchers have proposed a “windfall clause”, under which AI companies would promise to give away a large share of any enormous profits. The weakness is that a payment is not necessarily a vote: it hands over what the technology earns and leaves the decisions where they were.
Co-operatives and mutuals give members a vote. Training a leading model costs billions, far beyond what a co-op usually raises, but a member-owned service running on open models is within reach, and at least one UK group is already planning one. This is the closest modern version of Wiener’s offer: the people affected taking part in building the machines and keeping the gains.
Data collectives and unions give people a say over the data AI learns from. Mozilla’s Data Collective lets communities publish datasets on their own terms, and in 2026 it began licensing some of them commercially. In 2023 the Writers Guild and the actors’ union SAG-AFTRA won limits on how AI could be used on their work, and the TUC has proposed that unions act as stewards of their members’ data.
A model of shared ownership
None of these alternatives covers the whole of AI on its own, but each fits one layer well. Put together, they suggest a model of ownership that could work:
- Energy from public utilities and community-owned renewables, so that the places that power AI share in what it earns. Communities have done this before: in the last century many towns and rural areas ran their own electricity through co-operatives and municipal utilities.
- Computing power held publicly or shared, so that researchers, small organisations and co-ops are not dependent on a few cloud providers.
- Data governed by the communities and workers who produce it, through collectives and unions that set the terms for its use.
- Models that are open, with their weights and ideally their training data published, so anyone can inspect them, run them and build on them.
- Services owned by the people who use them, as co-operatives or mutuals running on those open models.
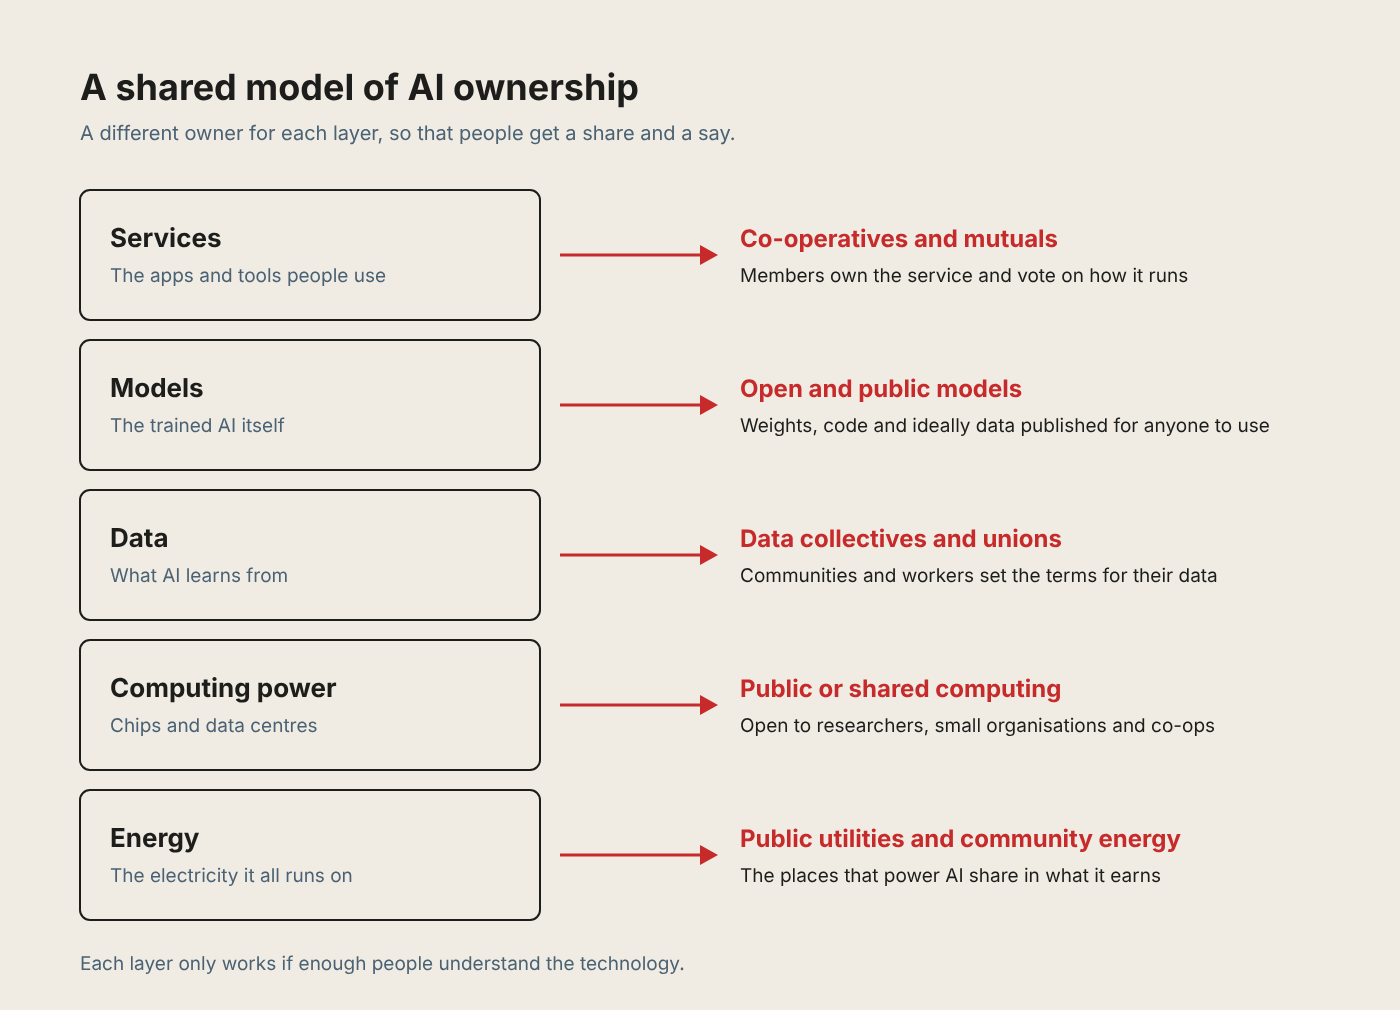
This model gives people both parts of ownership: a share in what AI earns and a say in what it does. It also depends on something none of the structures can supply by themselves. Each layer only works if enough people understand the technology well enough to use their votes, hold representatives to account and know what to ask for.
Steering starts with understanding
The word cybernetics comes from the Greek kybernētēs, the steersman, and steering is a useful way to think about this. You cannot steer something you do not understand, and understanding AI is far more open to ordinary people than most of them realise.
Open-weight models can be downloaded and run on a home computer, and publicly funded ones such as Apertus publish everything about how they were made. Around these models there are communities of people who share what they know for free: open-source developers, people who run home servers, archivists who preserve data that might otherwise disappear, and groups working on decentralised tools and on people’s control over their own data. Many of them are glad to help a beginner who asks a sensible question.
Not everyone has the time, the computer or the confidence to start, and those are often the people AI will affect most. There are easier routes in: many open models can be tried free in a browser, and libraries, community groups and unions are starting to run sessions on AI. You can also ask the models themselves. They are often patient teachers, provided you treat what they say as a starting point and check it, because they can be confidently wrong.
This basically means that anyone can make a start without being an engineer. It takes some curiosity and the habit of questioning what we hear about AI, whoever is saying it, including the machines. That habit is what turns ownership from a slogan into something people can take into their own hands.
Bringing people in
Wiener wrote to a union because a union could act where individual workers could not, and that is still true today. One person learning about AI gains some understanding, whilst a group of people learning together can action something with it. That group might be a reading circle at a local library, an online community where people help each other run models at home, a workplace group that asks how AI is being used on its members’ jobs, or a community that pools its data on its own terms. Every union, co-operative and collective in history started with a few people in a room. Today the room might be a group chat, or an online forum, and a say in AI can start the same way.
I wrote this article with the help of AI. I used it to consolidate my notes, find real examples of how AI is owned and governed, check facts and sources, draft and edit parts of the text, and sketch the diagrams. The ideas and arguments are mine, and I reviewed and reworked every part before publishing.